AI INFRASTRUCTURE

Compute for the next generation of AI.

Our long-term vision is scalable GPU infrastructure for model training, domain-model research and inference. We connect the future compute environment to the data, applications and operating requirements that will shape it.

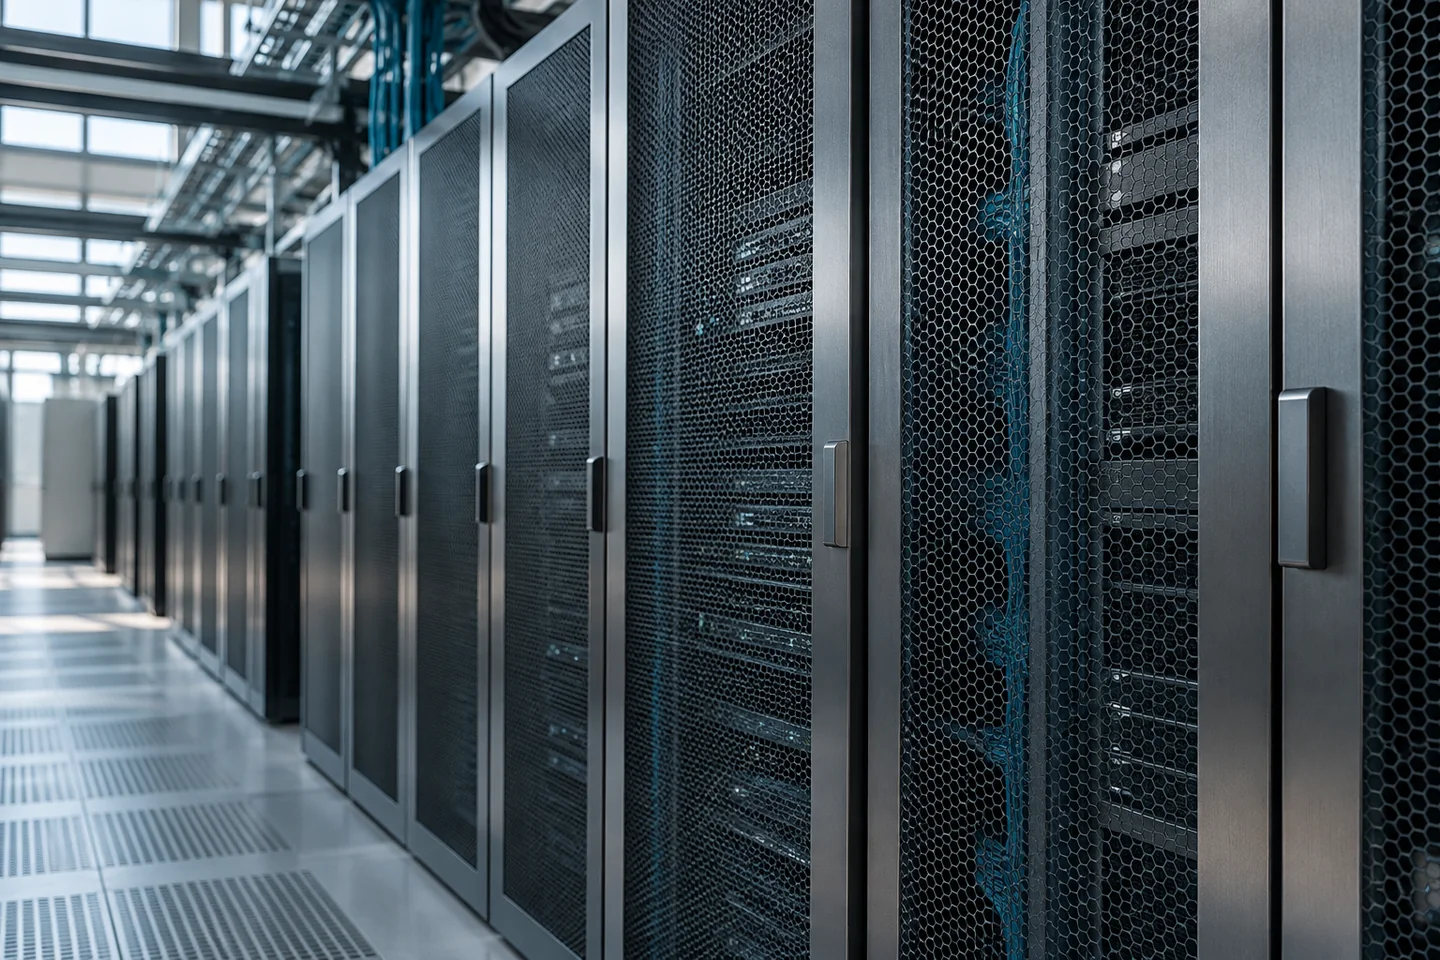
Rows of server cabinets in a bright data hall.

WORKLOAD ARCHITECTURE

Connect data, models and operations.

A reference architecture links the application to approved data, model services and the infrastructure required to operate it.

Workload requirements

Data, model and usage profile

Compute assessment

GPU, memory and interconnect

Deployment design

Provider and operational fit

Governance across every layer

Identity · Data boundaries · Monitoring · Change control

DEPLOYMENT OPTIONS

Customer environment / Public cloud / Hybrid design

INFRASTRUCTURE ADVISORY

Assessment today. A roadmap for future capacity.

Project-based architecture advisory provides the starting point for an infrastructure plan.

Architecture & feasibility advisory

Current project-based advisory can define the workload, assess deployment options and prepare a practical architecture roadmap.

  • Workload, data and model requirements
  • Compute, storage and network architecture assessment
  • Deployment options and operating responsibilities
  • Capacity planning and implementation dependencies
A path toward GPU hosting

GPU hosting is a planned extension of our infrastructure direction. Capacity, deployment arrangements and operating terms will be defined as the program develops.

  • Training, fine-tuning and inference requirements
  • Infrastructure and provider planning
  • Deployment and operating model design
  • A staged capacity and service roadmap

THE INFRASTRUCTURE VISION

From ambitious models to scalable compute.

A future infrastructure program spanning GPU clusters, data environments and AI compute racks, developed around training, research and inference workloads.

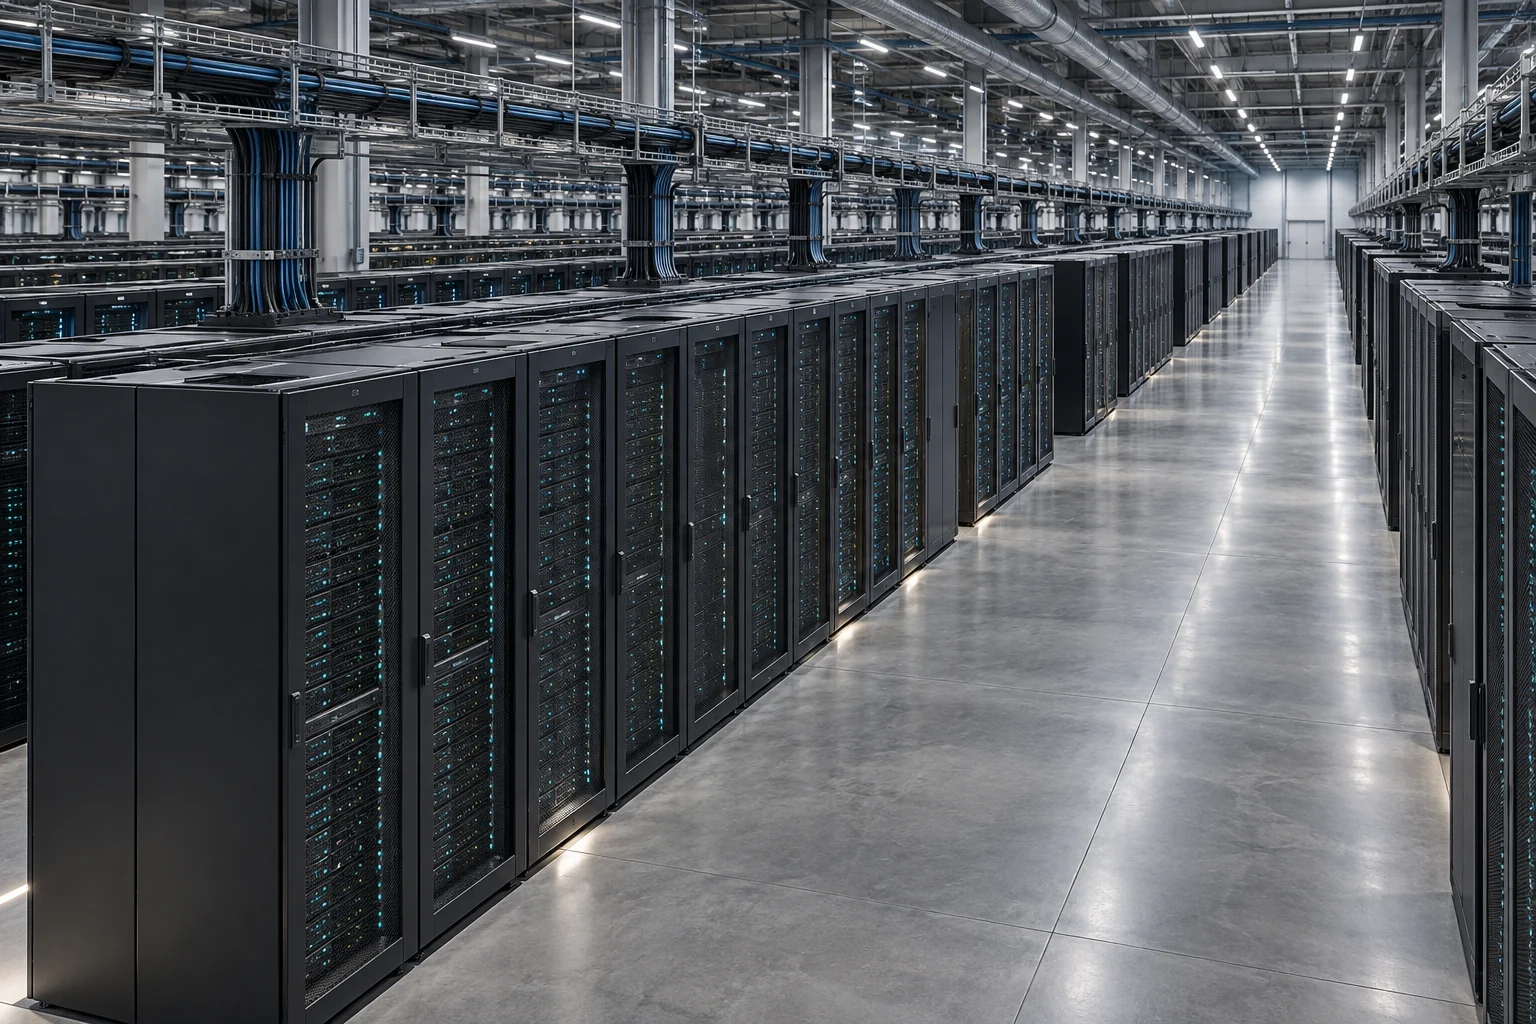
Multiple rows of server cabinets across a large data hall.

TRAINING AT SCALE

Large-scale GPU clusters

A 10,000-GPU-scale cluster vision for future model training and domain-model programs. The planning focus brings compute, networking, storage and workload scheduling into a staged capacity roadmap.

  • Distributed training architecture
  • Storage and data movement
  • Capacity planning and workload scheduling
Explore our domain-model direction
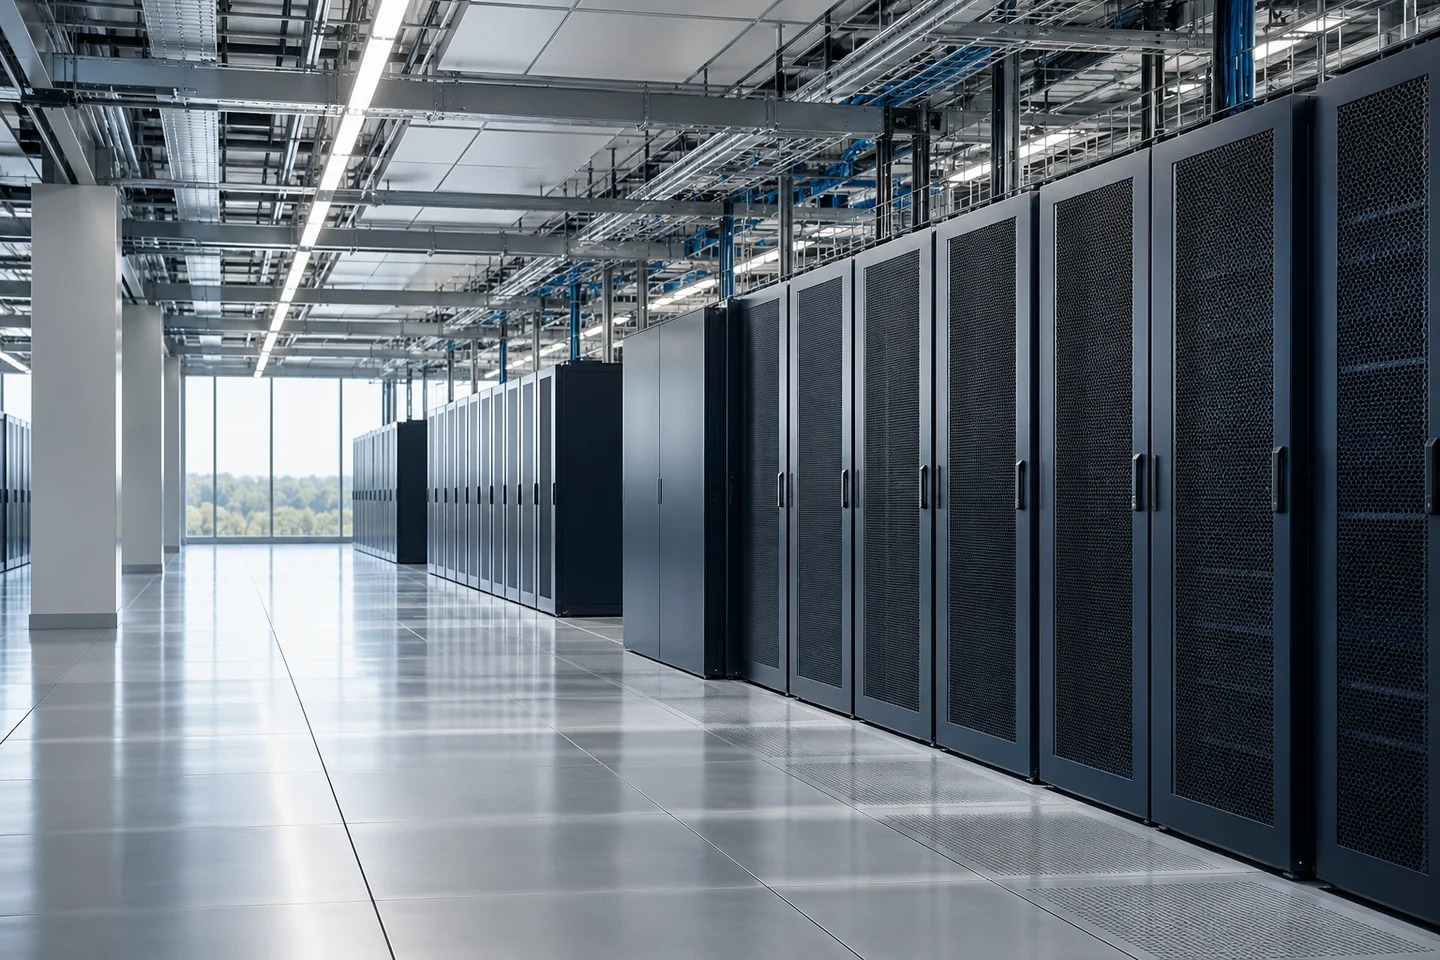
Server racks and overhead cable trays along a data-center aisle.

DOMAIN-MODEL RESEARCH

Purpose-built data environments

Future research environments would connect controlled data pipelines, dependable storage and scalable facility planning. This direction is intended to support our planned biopharmaceutical domain-model development alongside enterprise AI workloads.

  • Data access and research traceability
  • Research-to-compute workflows
  • Power, cooling and site planning
Explore AI for biopharmaceutical research
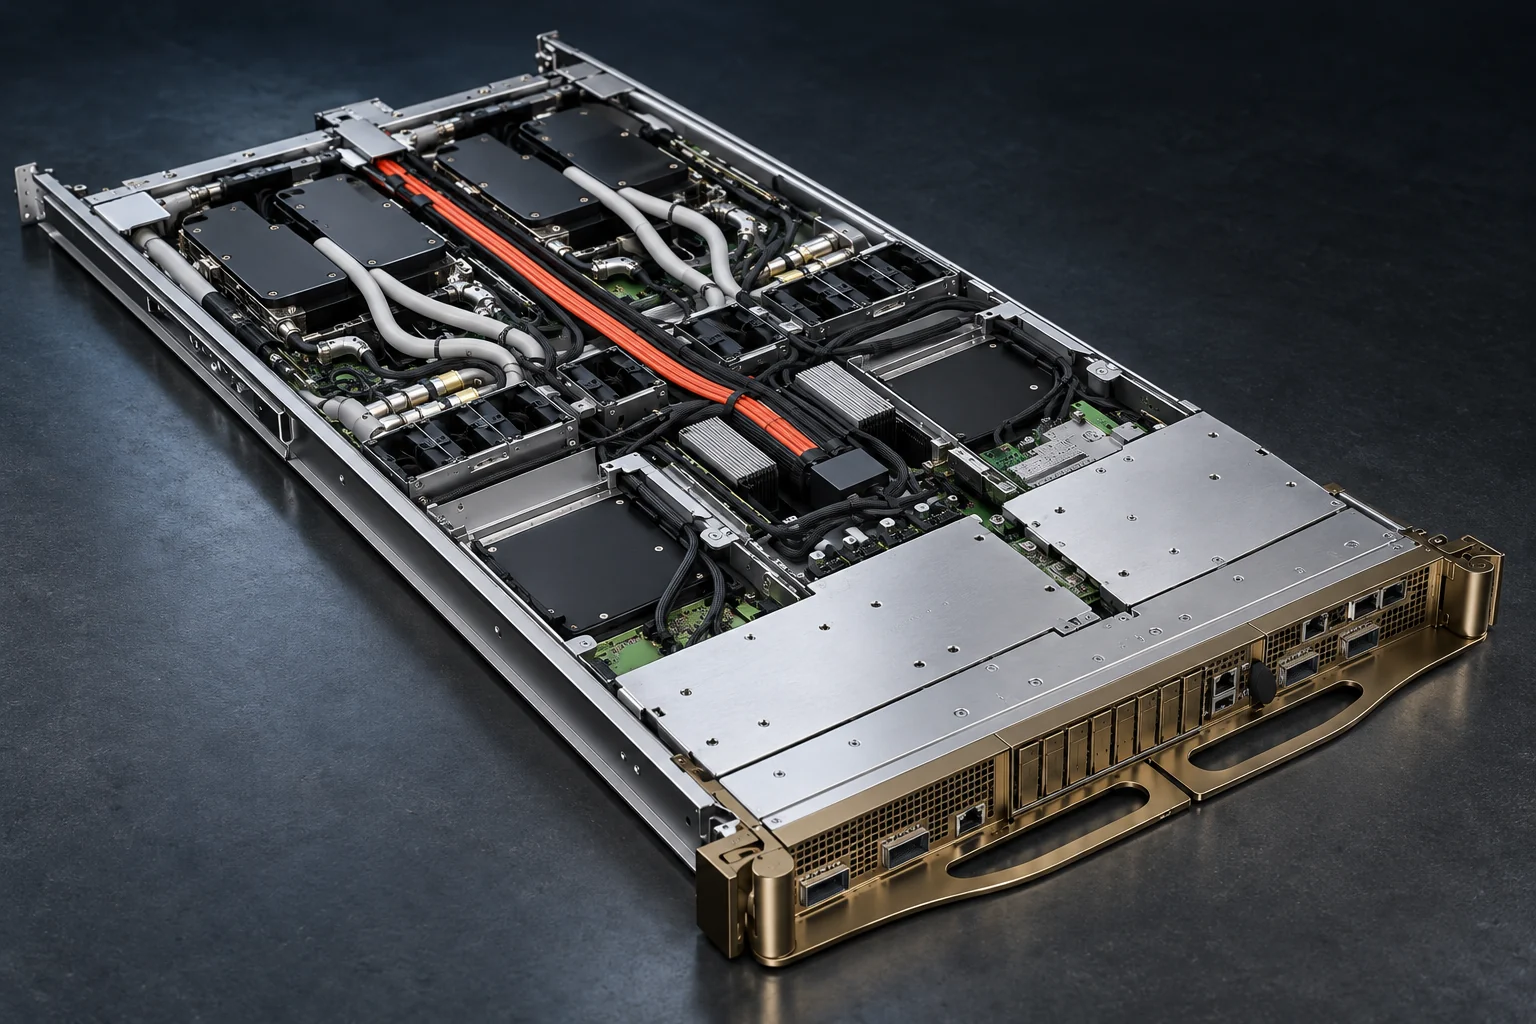
Open liquid-cooled compute tray with cold plates, coolant tubing and network interfaces.

INFERENCE & OPERATIONS

AI compute racks

Modular AI compute racks form a scalable deployment concept for model evaluation and inference. Future rack layouts would align GPU servers, network fabrics and serviceability with the requirements of each workload.

  • Rack-level system integration
  • Inference and evaluation operating models
  • Deployment, monitoring and maintenance planning
Explore infrastructure assessment

HOW WE WORK

A clear path from requirements to operation.

Each engagement starts with a defined scope. Delivery and operational responsibilities are agreed before implementation.

  1. Assess requirements

    Assess the business goal, users, existing systems and the decisions the project must support.

    OUTPUT

    Agreed requirements and initial scope

  2. Design the architecture

    Compare architecture and provider options, review dependencies and assign customer, service and provider responsibilities.

    OUTPUT

    Architecture, responsibility matrix and delivery plan

  3. Implement and validate

    Implement the contracted scope and evaluate it with agreed business, technical and acceptance criteria.

    OUTPUT

    Project deliverables and acceptance results

  4. Deploy, operate and hand over

    Prepare deployment, documentation and operating procedures. Provide ongoing operations only within the agreed contract scope, with a defined handover and escalation plan.

    OUTPUT

    Deployment, operations and handover plan

LET’S CONNECT

Plan the compute around your AI ambition.

Share the models, data and intended workload. We can discuss a scoped assessment and the infrastructure roadmap that follows.

Project inquiry

For enterprise software, cloud services or AI infrastructure assessment.

Discuss your requirements

Supplier collaboration

For cloud providers, infrastructure suppliers and technology delivery partners.

Discuss supplier collaboration